The Subtractive Secret to Cinematic Vocal Presence
In the world of high-stakes media production, the difference between an amateur project and a premium broadcast often lies in the spectral balance of the human voice. While many creators invest heavily in audio editing hardware, the most profound transformations happen within the surgical environment of the equalizer. An ‘expensive’ voiceover isn’t merely about the microphone; it is about the mastery of frequency masking and the elimination of resonant build-up that characterizes home-office recordings. Expert-level post-production requires a shift from additive boosting to subtractive precision, ensuring the vocal sits in a pocket that feels both intimate and authoritative.
Why Do Home Recordings Sound Boxy Despite High-End Microphones?
The primary culprit for a ‘cheap’ vocal sound is the 200Hz to 500Hz range, often referred to as the ‘boxiness’ or ‘mud’ zone. In untreated rooms, these frequencies accumulate, creating a hollow sound that even the best editing software cannot fix with a simple preset. To combat this, one must apply a narrow Q-factor cut to identify the specific resonant frequency of the recording space. You might find that fixing a hollow-sounding voiceover in post starts with identifying these standing waves. By taming these frequencies by just 2dB or 3dB, you allow the natural harmonics of the voice to emerge without the clutter of room acoustics.
The 12kHz Air Band and the Illusion of Depth
Professional engineers often speak of ‘air’—that shimmering, high-frequency clarity that makes a narrator sound like they are whispering directly into the listener’s ear. This isn’t achieved by a generic treble boost, which often introduces harshness and sibilance. Instead, it requires a gentle high-shelf boost starting around 10kHz to 12kHz. However, this must be balanced with careful de-essing. According to research published by the Audio Engineering Society (AES), the intelligibility of speech is highly dependent on the 2kHz to 5kHz range, but the perceived quality and luxury of the sound are found in the upper-harmonic extensions. If you find your signal losing body during this process, it is often the real reason your audio sounds thin after compression.
Kill the Rumble Without Destroying the Soul
A common mistake in video editing workflows is the aggressive use of a high-pass filter. While removing sub-bass rumble is essential, setting your cutoff too high (above 80Hz or 100Hz for male voices) strips away the foundational resonance that provides authority. Advanced editors use a slope of 12dB or 18dB per octave rather than a brick-wall cut to maintain a natural roll-off. This preservation of the fundamental frequency is what gives a voice its ‘weight.’ For those moving between photo editing and video, think of this as the audio equivalent of maintaining shadow detail while crushing the blacks for contrast. If you are struggling with clarity, learn how to remove background hiss without losing vocal clarity before you touch the EQ, as noise floor issues can often trick your ears into making poor equalization choices.
As you refine your signal chain, consider how your hardware interacts with your software. Using the right editing accessories, such as high-impedance headphones or calibrated monitors, is vital to hearing these subtle shifts. If you have specific questions about your unique vocal frequency profile, feel free to share your setup and contribute professional insights to our growing community of sound designers.
Ditch the Single Compressor for a Multi-Stage Workflow
Beyond the surgical precision of EQ, the most misunderstood weapon in a creator’s arsenal is the dynamic processor. Many editors fall into the trap of over-squashing their signal with a single high-ratio compressor, which is precisely why your audio compressor is making your voice sound worse. A transparent, high-end vocal requires a gentle touch; think of it as a sculptor lightly sanding a surface rather than a sledgehammer breaking stone. By using a series of compressors with low ratios—around 2:1 or 1.5:1—you can level out the performance gradually. The first compressor in the chain should focus on catching fast peaks with a quick attack, while the second acts as a leveler with a slower release to provide a consistent, velvet-like texture that remains intelligible even on smartphone speakers.
How Do You Maintain Vocal Authority When Music Fights for the Same Space?
The battle between a voiceover and a background track is often won in the mid-range. Instead of merely lowering the volume of the music and losing its energy, use frequency-conscious sidechaining. By carving out a subtle 3dB dip in the music track specifically between 1kHz and 3kHz only when the narrator speaks, you create a dedicated ‘pocket’ for the dialogue. This approach is superior to broad volume dipping because it allows the track to feel powerful without masking the narrator. If you notice your signal clipping during these adjustments, it is time to revisit the gain staging move that saves your podcast from digital clipping before finalizing your mix.
Thicken Your Narrative with Parallel Vocal Processing
For projects that require a ‘larger-than-life’ presence, traditional serial compression might not be enough. This is where parallel processing, often called New York compression, becomes indispensable. By creating a duplicate of your vocal track and applying aggressive, heavy compression to the copy while leaving the original dry, you can blend the two signals to achieve the best of both worlds: the transient punch of the raw audio and the dense, consistent weight of the compressed signal. This technique ensures the voice never feels ‘squashed’ but retains a professional density that cuts through complex sound designs easily. #IMAGE_PLACE_HOLDER_B#
Purge Technical Flaws Before Applying Creative Processing
No amount of compression or parallel saturation can hide technical imperfections like mouth clicks or harsh sibilance. In fact, dynamic processing often amplifies these flaws. Successful editors prioritize cleaning the signal at the start of the chain. This involves learning how to remove clicking sounds from dialogue edits and applying frequency-dependent attenuation for ‘S’ sounds. If your vocal feels like it is piercing the listener’s ears, you need the fix for sibilance that cuts through a podcast mix before you even think about the final render. Technical experts at Sound on Sound suggest that the human ear is most sensitive to the 3kHz region, meaning even a slight over-emphasis here can cause listener fatigue during long-form content.
Achieving a cinematic vocal is an iterative process of cleaning, shaping, and then enhancing. Each step builds on the last, ensuring that your audio matches the high visual fidelity of your video projects. Which part of your vocal chain gives you the most trouble? Share your workflow in the comments below or reach out to contribute professional insights to our growing library of post-production strategies.
Stop Your Vocal From Vanishing in Mono Mixes
In the relentless pursuit of a ‘wide’ and immersive soundstage, many editors inadvertently sacrifice the core integrity of their dialogue. While stereo-widening tools in modern editing software can make a voice feel expansive, they often introduce destructive phase interference. When that same audio is played back on a smartphone or a mono-summed smart speaker, the vocal can thin out or even disappear entirely. To prevent this, expert sound designers utilize mid-side (M/S) processing rather than simple panning. By keeping everything below 300Hz strictly in the ‘mid’ channel, you anchor the vocal’s authority in the center. The ‘side’ channel should only contain the subtle high-frequency reflections or harmonic extensions that provide the illusion of space without compromising the signal’s foundation.
Can Harmonic Saturation Replace Traditional EQ for Modern Dialogue?
Oftentimes, a vocal feels dull not because it lacks volume in the high frequencies, but because it lacks harmonic complexity. Instead of pushing a digital high-shelf boost—which can quickly become brittle and fatiguing—advanced creators turn to saturation. Unlike equalization, which simply increases the gain of existing frequencies, saturation generates entirely new overtones based on the fundamental signal. According to technical guides from Universal Audio, vintage-style saturation from tube or tape emulations adds a ‘density’ that makes a voiceover feel more physically present. This psychoacoustic trick fills the spectral gaps that a standard equalizer cannot reach, resulting in a narrative that sounds ‘expensive’ even on lower-quality playback devices. 
Give Your Narrator a 3D Profile with Mid-Side Processing
Stepping beyond basic audio editing requires a shift in how you perceive the acoustic space. A common professional secret for high-end commercials is the application of selective reverb. Rather than applying a single reverb to the entire vocal track, try creating an auxiliary bus with a high-pass filter set at 600Hz. Apply a short, high-density ‘room’ reverb to this bus and blend it back in. This ensures that the low-end fundamental stays dry and punchy, while the upper-mid intelligibility frequencies enjoy a sense of three-dimensional depth. It’s an approach often mirrored in photo editing, where one might sharpen the edges of a subject while keeping the core shadows soft to maintain a sense of realism and focus.
Why the Proximity Effect is Your Best Friend and Worst Enemy
The closer a narrator gets to a directional microphone, the more the bass response is exaggerated—this is the proximity effect. While it provides that ‘radio voice’ gravitas, it can also lead to inconsistent low-end buildup if the talent moves even an inch during the recording. To manage this in post-production, look for dynamic EQ. Unlike a static cut, a dynamic EQ only activates when the bass frequencies cross a certain threshold, taming the ‘boom’ during loud passages while preserving the warmth during softer moments. Using the right editing accessories, like a high-quality pop filter and a dedicated boom arm, can minimize these fluctuations at the source, but the final polish always happens in the software. If you have mastered your signal chain and want to contribute professional insights on your specific vocal processing order, our community of creators would love to hear your perspective.
Automate the Energy Not Just the Volume
Relying solely on a compressor to level out a performance is a recipe for a flat, lifeless mix. The truly elite video editing professionals use ‘vocal riding’ or manual volume automation before the signal even hits the first compressor. By leveling the peaks and valleys of the performance by hand, you allow the compressor to work consistently throughout the entire track. This maintains the emotional ‘breath’ of the speaker while ensuring that every syllable is perfectly audible against a complex sound design. This meticulous attention to detail is what separates a standard YouTube video from a cinematic experience that demands the listener’s full attention.
Sharpen the syllables with precision transient shaping
In the final stages of a high-end audio editing workflow, the difference between a voice that sits on top of a mix and one that lives inside it is often found in the transients. While compression controls the overall dynamic range, transient shaping allows you to manipulate the initial ‘hit’ of consonants without affecting the tonal body of the vowel. If your narrator sounds slightly muffled or lacks the bite needed for an energetic commercial, a dedicated transient designer can emphasize the attack of the plosives. This creates a tactile, physical presence that cuts through dense music beds. Conversely, if the speaker’s mouth noises are too distracting, softening the sustain can reduce the tail of breaths and room reflections, providing a cleaner canvas before you even touch your editing software gates.
How do you solve phase cancellation in complex interview setups?
When recording a podcast or a documentary with multiple microphones, editors often face the destructive reality of phase interference. If two microphones pick up the same voice at slightly different times, certain frequencies will cancel each other out, leading to a thin, hollow, or ‘comb-filtered’ sound. This is particularly prevalent when using editing accessories like desktop stands that reflect sound off a hard surface. To fix this, you must zoom in at the sample level and manually nudge the waveforms until the peaks and troughs align perfectly. For larger projects, professional tools can automate this time-alignment, ensuring that the combined signal sounds robust and authoritative rather than weak and distant. 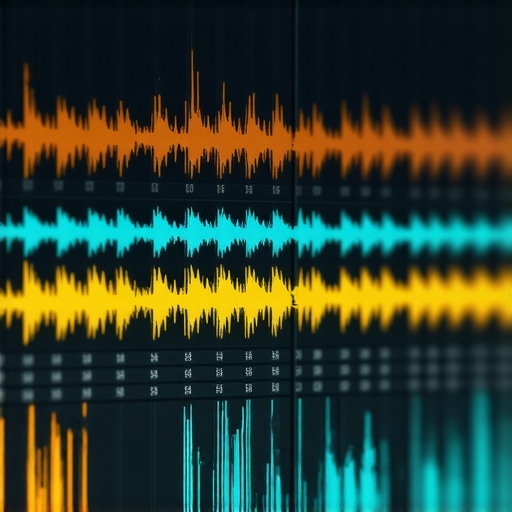
Conquer the uncanny valley of dry studio recordings
A frequent hurdle in video editing for cinema is the ‘dead’ sound of a dry studio booth, which often feels disconnected from the visual environment. To bridge this gap, advanced sound designers utilize convolution reverb. Unlike traditional algorithmic reverbs that simulate space using mathematical formulas, convolution reverb uses impulse responses (IRs)—actual recordings of real spaces like cathedrals, tiled bathrooms, or forest clearings. By ‘imprinting’ the acoustic characteristics of the filming location onto your studio-recorded dialogue, you create a seamless psychological link for the audience. This level of realism is what distinguishes premium streaming content from standard web-based productions. It requires a deep understanding of the editing software‘s internal routing to ensure the dry signal remains intelligible while the ‘wet’ convolution tail provides the necessary environmental context.
Anchor your final mix to global loudness standards
The ultimate sign of a seasoned professional is a mix that sounds consistent across every device, from high-end home theaters to budget smartphones. Achieving this requires moving beyond simple peak meters and embracing LUFS (Loudness Units relative to Full Scale). According to the international standards set by the International Telecommunication Union (ITU), maintaining a specific integrated loudness—typically -14 LUFS for streaming or -23 LUFS for broadcast—is essential for avoiding the aggressive ‘auto-leveling’ applied by platforms like YouTube or Spotify. By mastering your final gain staging to these specifications, you ensure your creative intent remains intact, preventing the platform’s algorithms from squashing your carefully crafted dynamics. This technical rigor, combined with the right photo editing-like attention to detail in your visual metadata, ensures your project meets the highest professional benchmarks.
Refining these advanced textures is a continuous journey of listening and adjusting. Whether you are battling phase issues or trying to match a voiceover to a specific room, the tools are only as good as the ears using them. Are you ready to elevate your sound design to a cinematic standard? Join our community of creators today to share your most effective signal chains and discover new ways to push the boundaries of modern media production.
Expert Insights & Advanced Considerations
Manual Sample Alignment Beats AI Every Time
While many modern plugins promise to align multi-mic setups with a single click, they often miss the nuanced timing of low-frequency transients. To achieve true phase coherence, you must zoom in to the sample level within your editing software and manually align the peaks of both waveforms. This is the only way to ensure your dialogue retains its foundational weight. If you’ve ever wondered why your signal sounds thin despite a great mic, it’s often because you need to learn how to fix phase cancellation in dual-microphone recordings using manual nudging rather than relying on automated algorithms.
Why You Should Fear the -14 LUFS Ceiling
The industry fixation on -14 LUFS as a target for streaming can be a trap. Mastering strictly to a loudness number often results in a loss of the ‘crest factor’—the distance between your peaks and the average level—which gives audio its life and punch. Instead of just cranking the gain, focus on dynamic transparency. If your final file sounds flat on a phone, you are likely hitting the limiter too hard, which is often why your audio exports are too quiet for Spotify or other platforms that normalize based on perceived energy rather than simple peaks.
Stop Treating Sibilance as a Software Problem
A de-esser is a reactive tool, not a preventative one. Highly skilled engineers know that ‘S’ sounds are most aggressive when the narrator’s delivery is inconsistent. Before you reach for a plugin, check the physical placement of your editing accessories, particularly the angle of the microphone. If the damage is already done, avoid the ‘lisp’ effect by using frequency-dependent gain reduction that targets the 5-8kHz range with surgical precision. Understanding the proper way to use de-essers on aggressive sibilance will save your high-end clarity without making the narrator sound unnatural.
Curated Expert Resources
The Audio Engineering Society (AES) E-Library: This is the ultimate repository for peer-reviewed research on speech intelligibility and room acoustics. It is essential for those who want to understand the ‘why’ behind frequency masking.
Sound on Sound’s Technical Archives: For decades, SOS has provided the most granular breakdowns of audio editing signal chains used in professional studios. Their deep dives into parallel processing are industry standards.
Bob Katz’s Mastering Audio: The Art and the Science: This text is widely considered the bible of digital audio. It offers definitive guidance on gain staging, monitoring levels, and the psychoacoustics of human hearing.
Final Expert Perspective
True cinematic presence isn’t an accident; it is the result of a disciplined workflow that prioritizes technical cleanliness before creative enhancement. By moving beyond basic presets and mastering the surgical nuances of audio editing, you transform a standard recording into a professional narrative that commands attention. Every choice, from sample-level alignment to LUFS-aware gain staging, contributes to the final authority of your project. As you refine your own process, we invite you to contribute professional insights and join the conversation on how to push the boundaries of modern sound design.